Sdcb.Arithmetic
.NET numerics for the AI era: GMP / MPFR-class arbitrary-precision arithmetic in pure managed C#. No native DLLs — and AVX-512 / AVX2 / NEON / WASM SIMD all the way down.
dotnet add package Sdcb.Arithmetic
Three types
GMP and MPFR power, .NET ergonomics
All three implement .NET generic math (INumber<T>, IBinaryInteger<T>, IBinaryFloatingPointIeee754<T>) and interoperate with System.Numerics.BigInteger. Every BigInt operation is cross-checked against BigInteger and native GMP; every Real function bit-for-bit against MPFR in every rounding mode.
using Sdcb.Arithmetic;

// BigInt ≈ GMP mpz_t
BigInt p = BigInt.Pow(2, 521) - 1;               // Mersenne prime M521
bool prime = p.IsProbablePrime();                // BPSW + Miller–Rabin
BigInt m = BigInt.ModPow(3, p - 1, p);           // 1, Fermat says hi

// BigRational ≈ GMP mpq_t, always canonical
BigRational q = new BigRational(1, 3) + new BigRational(1, 6);   // 1/2

// Real ≈ MPFR mpfr_t: correctly rounded, five rounding modes
Real.DefaultPrecision = 256;                     // bits
Real pi = Real.Pi();
Real e = Real.Exp(pi * Real.Sqrt(163));          // 262537412640768743.99999999999925…
Real lo = Real.Sqrt(2, 64, RealRounding.TowardNegative);
Real hi = Real.Sqrt(2, 64, RealRounding.TowardPositive); // √2 ∈ [lo, hi], guaranteedLab
Every number below is computed live, in your browser, by Sdcb.Arithmetic
The very same NuGet package, compiled to .NET WebAssembly (AOT + SIMD128), running in a Web Worker.idle
① How double lies to you
- double
- …
- Real · 200 bit
- …
Because the 0.1 inside a double is actually:
…
- double
- …
- Real · 256 bit
- …
It is almost an integer — double can’t see the “almost”, and even gets the last integer digits wrong.
- double
- …
double returns something around 10²¹ — without any warning. The true value is −0.8273960599…, and you need 122+ bits to see it.
- √2 ≥
- …
- √2 ≤
- …
Only 64 bits, but rounding TowardNegative / TowardPositive yields an interval that provably contains the true value — the basis of interval arithmetic.
Every rounding error pushes the sequence towards the wrong fixed point, 100. More precision holds out longer — arbitrary precision isn’t “a few more decimals”, it’s whether the answer is right at all.
② The truth about chaos
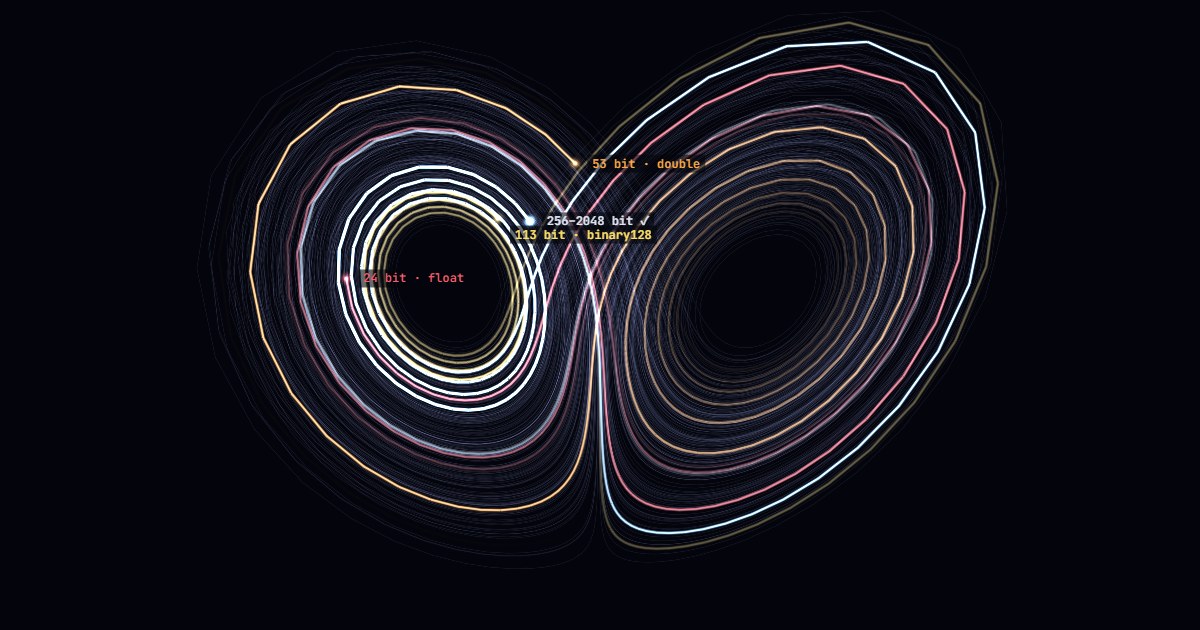
The Lorenz system: same initial point (1, 1, 1), same RK4, same step 0.005 — the only difference is how each step rounds. Once float and double drift away, which one is real? Real integrates at 256 and 1024 bits, and the two runs agree throughout: that is the truth.
- float departs
- …
- double departs
- …
- |double − Real|
- …
- Real 256 vs 1024
- …
- Real time 256 / 1024
- …
Distance from Real (log scale): the error grows tenfold every few time units until it swallows the trajectory.
Full screen · 24 → 2048 bit
Precision ladder · butterfly swarm · three bodies
Seven precisions leave the same point and defect one by one — every extra bit buys ~0.76 time units of future. Plus 5 attractors, live parameters and the Pythagorean three-body problem.
③ π speed-run and a big-number race
- Real.Pi · correctly rounded
- –
- to decimal
- –
- Chudnovsky · BigInt
- –
- both agree
- –
Left: each digit d is one step in direction 36°·d — a random walk of 100k steps.
Performance
Far ahead of BigInteger, close behind native GMP
AMD Ryzen 7 5800X (AVX2), .NET 10, operands of 1–65,536 64-bit limbs.Full tables and methodology
| Operation | Speed-up over BigInteger | Time vs native GMP 6.3 (lower is better) |
|---|---|---|
| Multiply | 1.9–28× | 1.3–1.6× |
| Divide 2N/N | 2.2–5.9× | 1.5–2.6× |
| Modular power | 4.2–7× | 1.3–2.8× |
| GCD | 1.5–5.8× | 0.9–1.4× |
| Add / sub / shift | 2.5–11× | 1.1–3.1× |
| Decimal ToString / Parse | up to 16× / 4× | 0.5–1.9× |
Real vs native MPFR 4.2 (53–16384 bits, both correctly rounded): add/mul 1.3–2.5×, div/sqrt 1.3–3.3×, exp/sin/atan 0.9–1.8×, log/pow 1.6–2.7×.
Docs
- Examples: 1M digits of π, RSA, rounding, generic math
- Real: features and functions
- GMP / MPFR → BigInt / Real API mapping
- Design, algorithms and verification
Looking for the old GMP/MPFR P/Invoke bindings? They moved to sdcb/Sdcb.Arithmetic.
Community
Chat with us in the .NET骚操作 group
Questions, ideas, benchmark results — all welcome.